Abstract
Vision-language models such as CLIP enable zero-shot classification from arbitrary class names, but under test-time corruptions, their visual encoder projects distorted features onto incorrect textual anchors with high confidence: a phenomenon we term modality bias. Standard entropy minimization reinforces these overconfident errors, which creates a confirmation-bias loop and collapses the predicted label distribution.
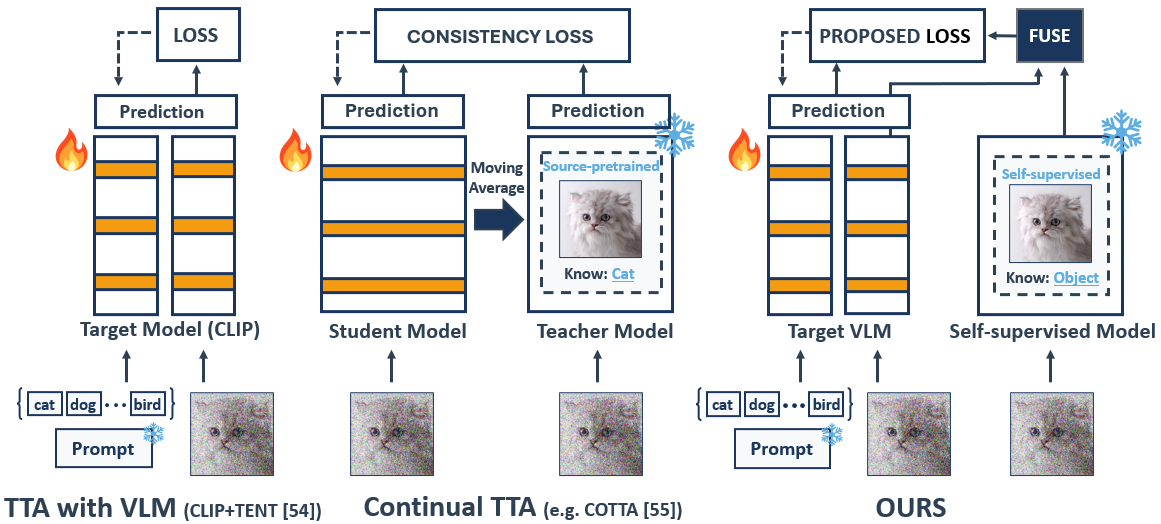
We propose an online test-time adaptation (TTA) method that breaks this loop at three levels. At the representation level, a frozen self-supervised backbone (e.g., DINO v2) is combined with CLIP through a cross-covariance logit ensemble. CLIP text prototypes are projected into the feature space of this text-free backbone, so the self-supervised branch classifies native image features and is less affected by the text bias of CLIP. At the optimization level, a gated test-time information-maximization objective pairs per-sample sharpening with batch-level diversity, while an adaptive gate excludes unreliable samples from the gradient. At the prediction level, an online logit adjustment corrects the residual class-distribution skew.
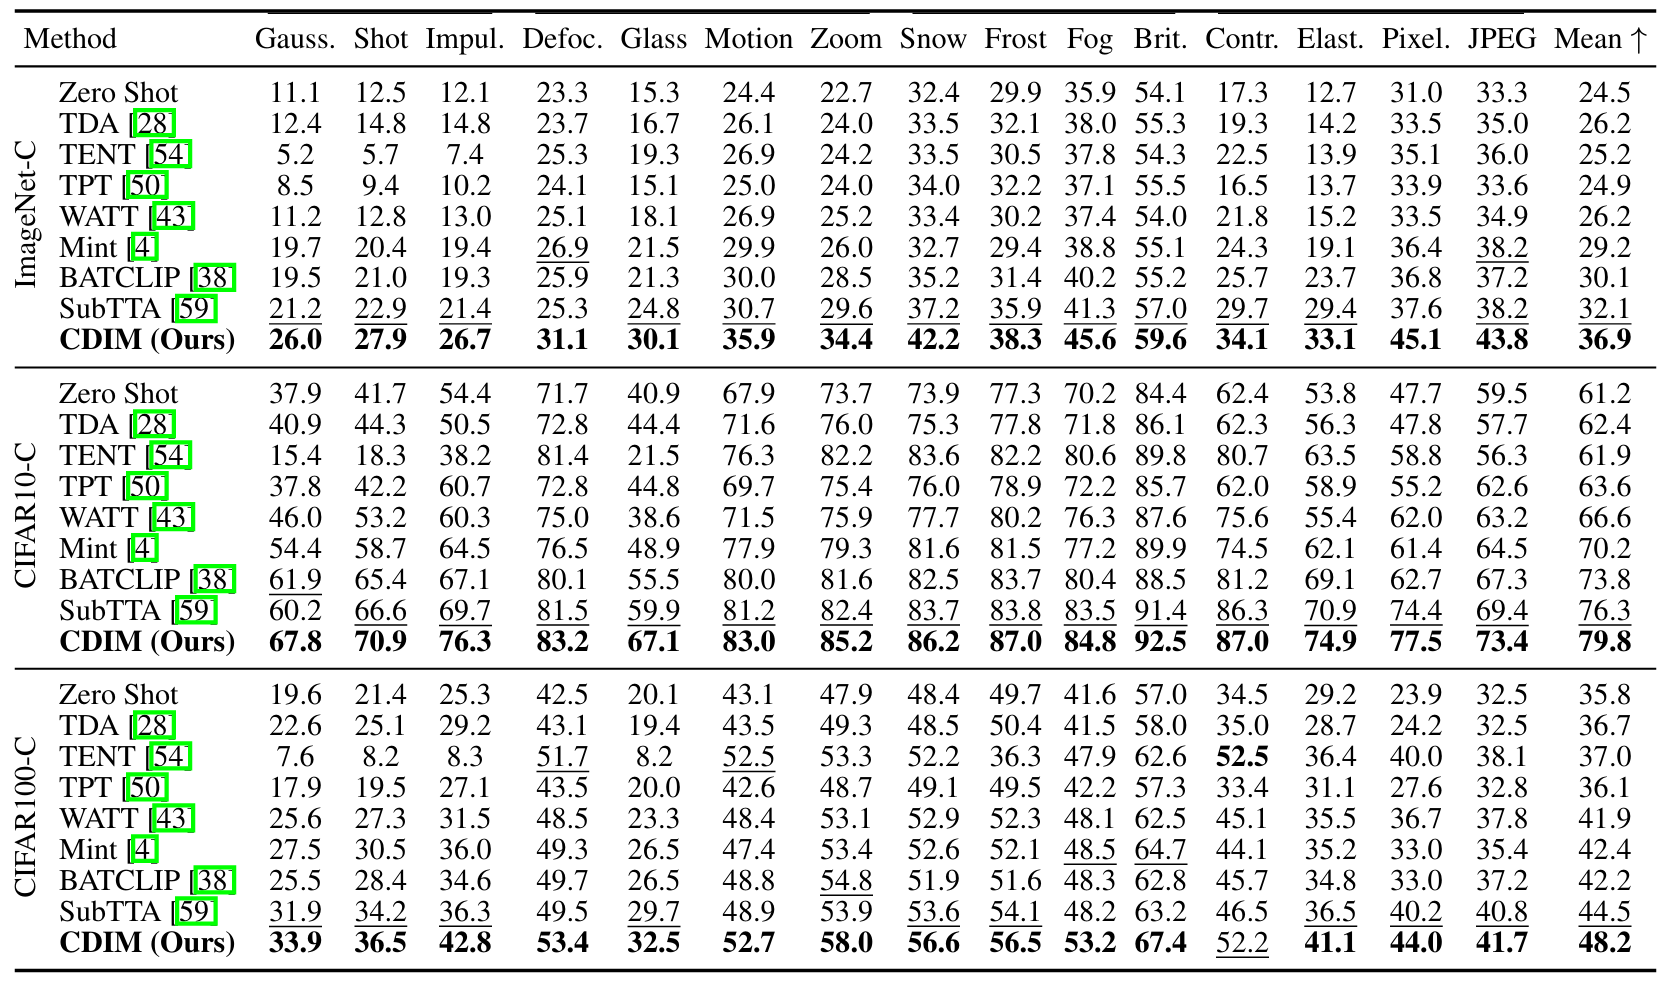
CDIM outperforms the compared CLIP-based online TTA baselines on ImageNet-C, CIFAR10-C, and CIFAR100-C, and remains competitive in continual and mixed-domain TTA. Extensive analyses and ablation studies verify the contribution of each of its components.
Analyses & Results
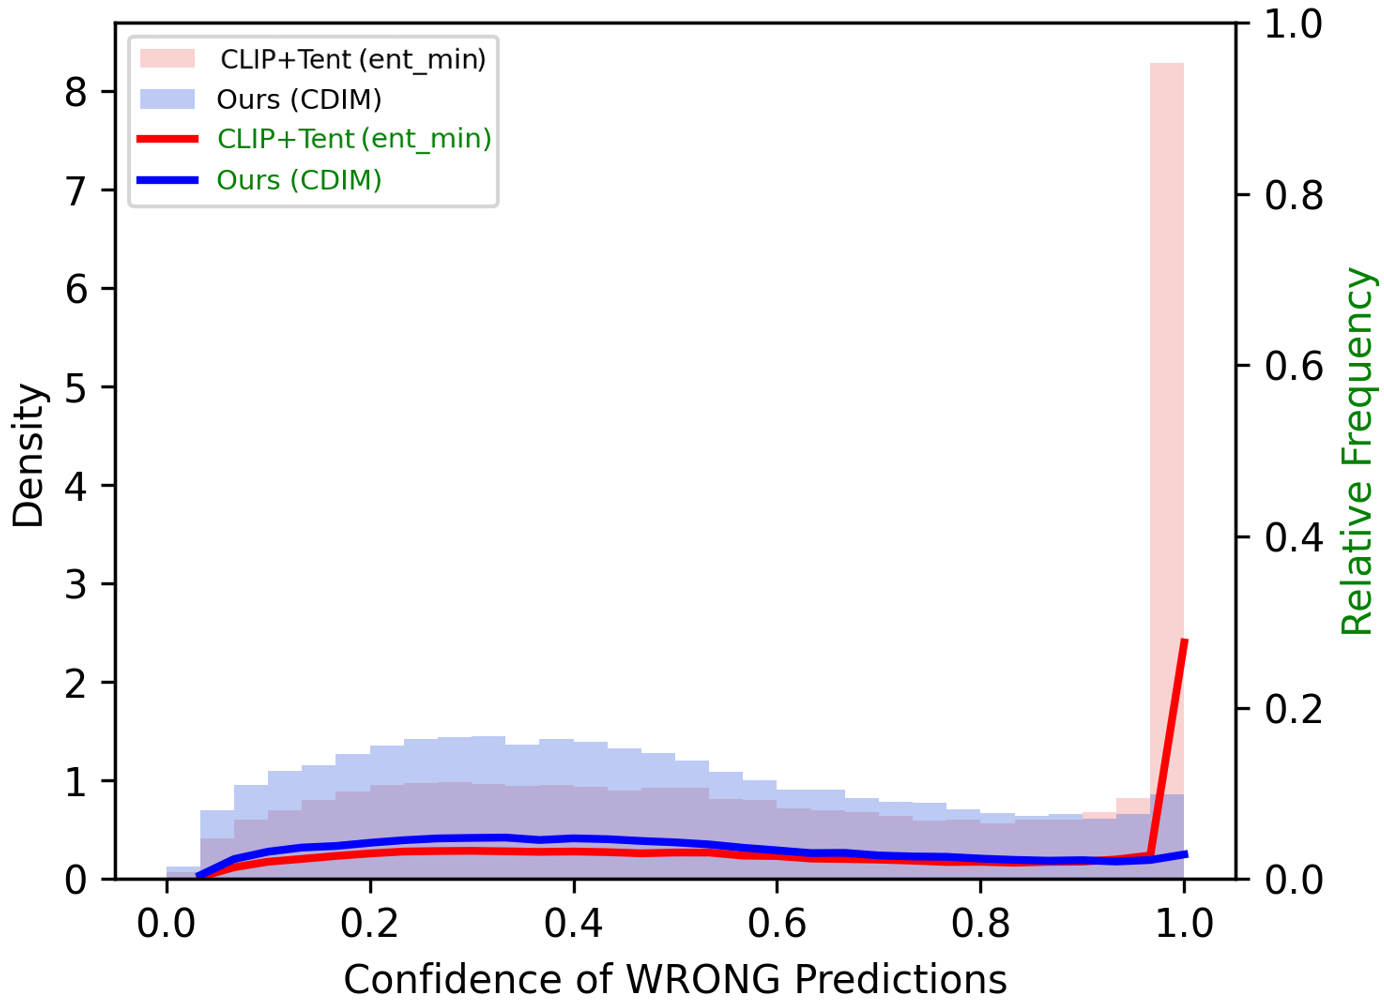
Confidence of Incorrect Predictions: On ImageNet-C, CLIP optimized with entropy minimization concentrates its errors at near-perfect confidence. CDIM shifts the confidence of incorrect predictions toward moderate values.
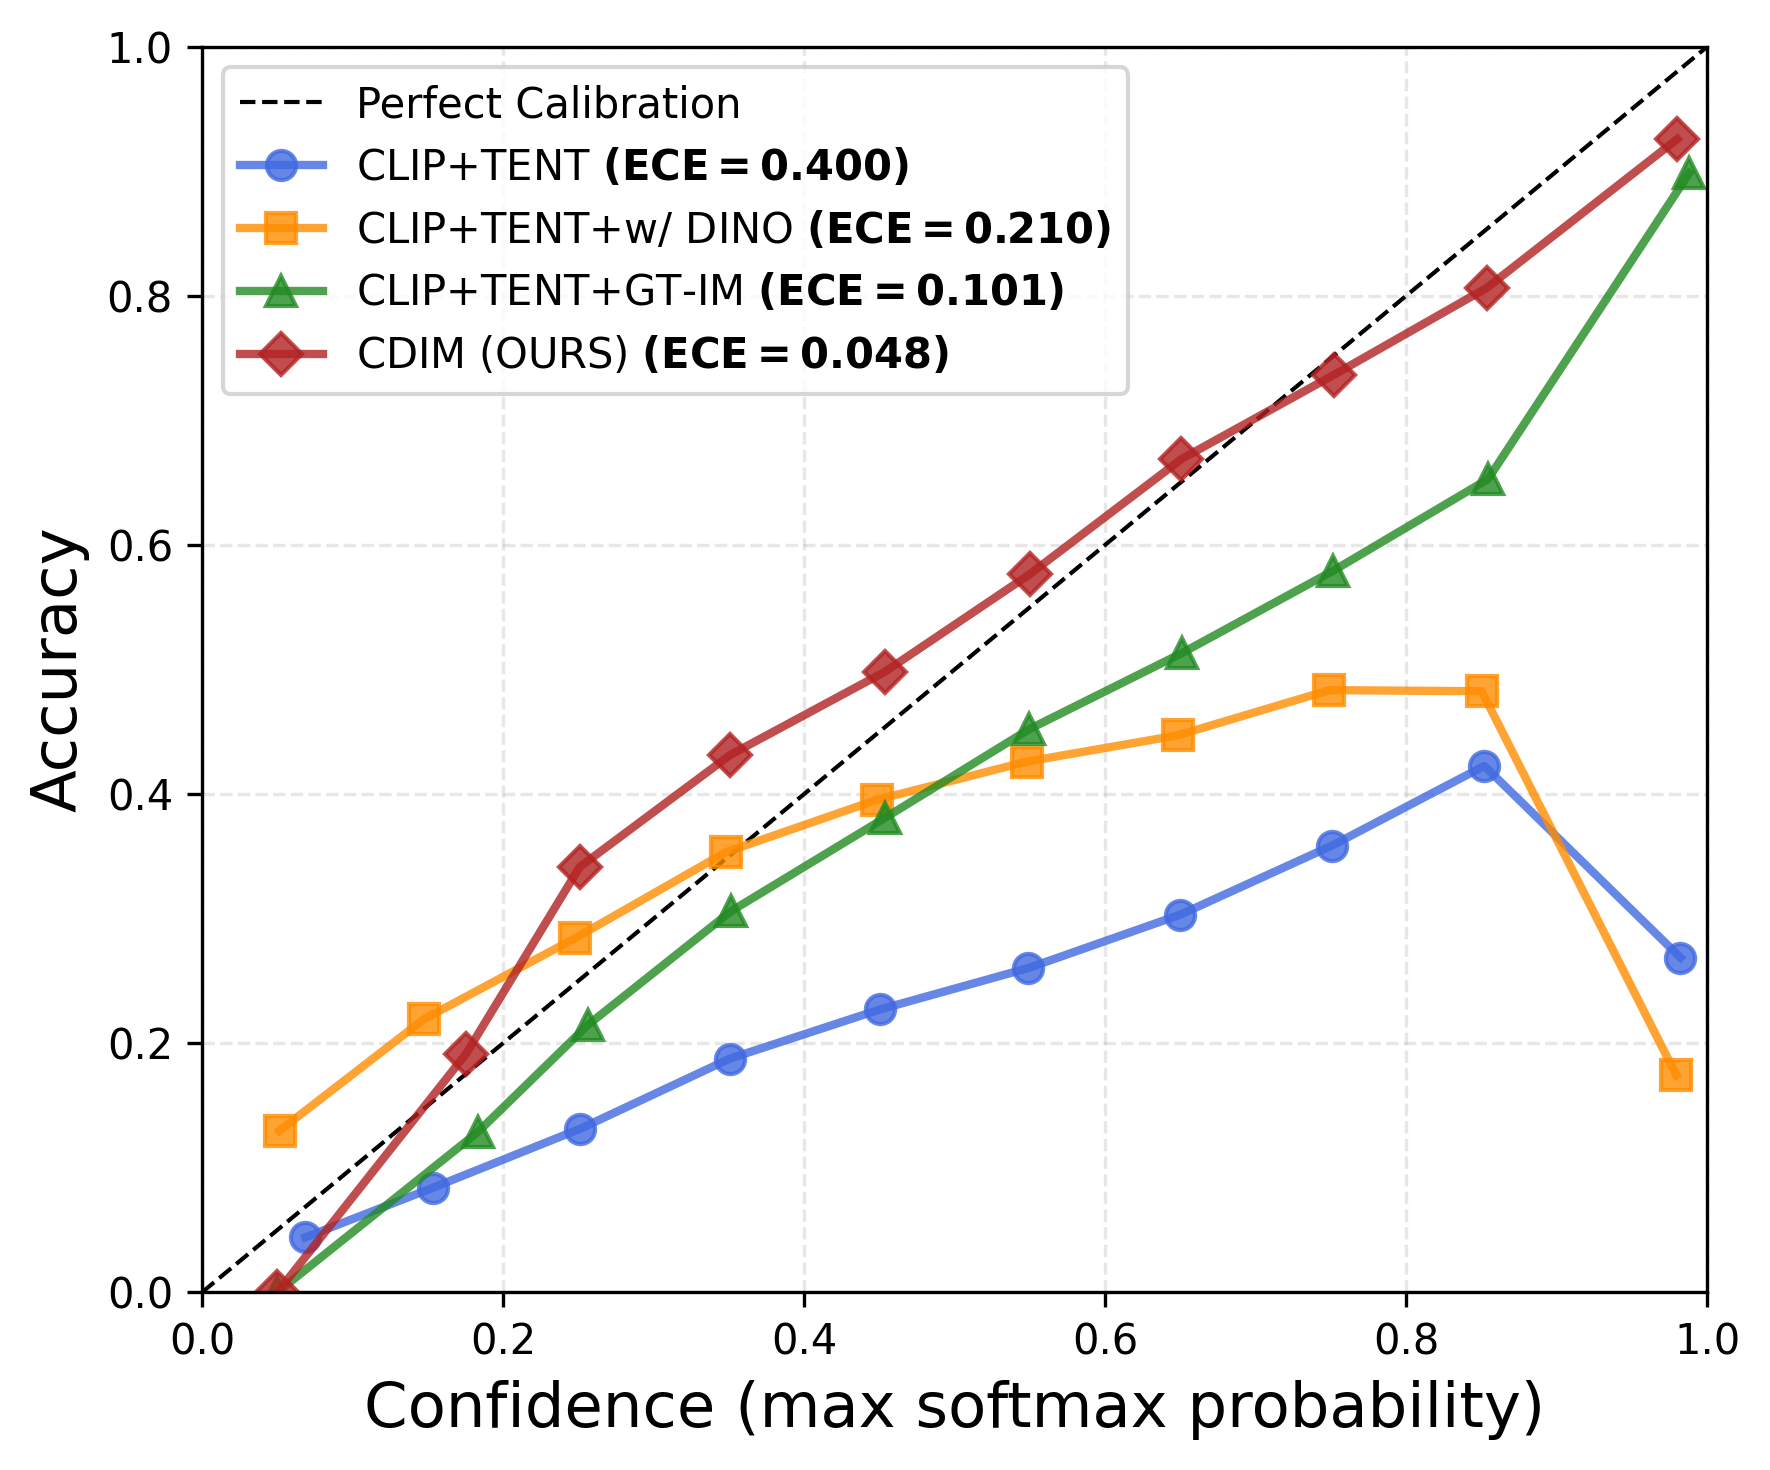
Reliability Diagram: CLIP+TENT is severely over-confident (ECE 0.400). CDIM lowers the ECE to 0.048.
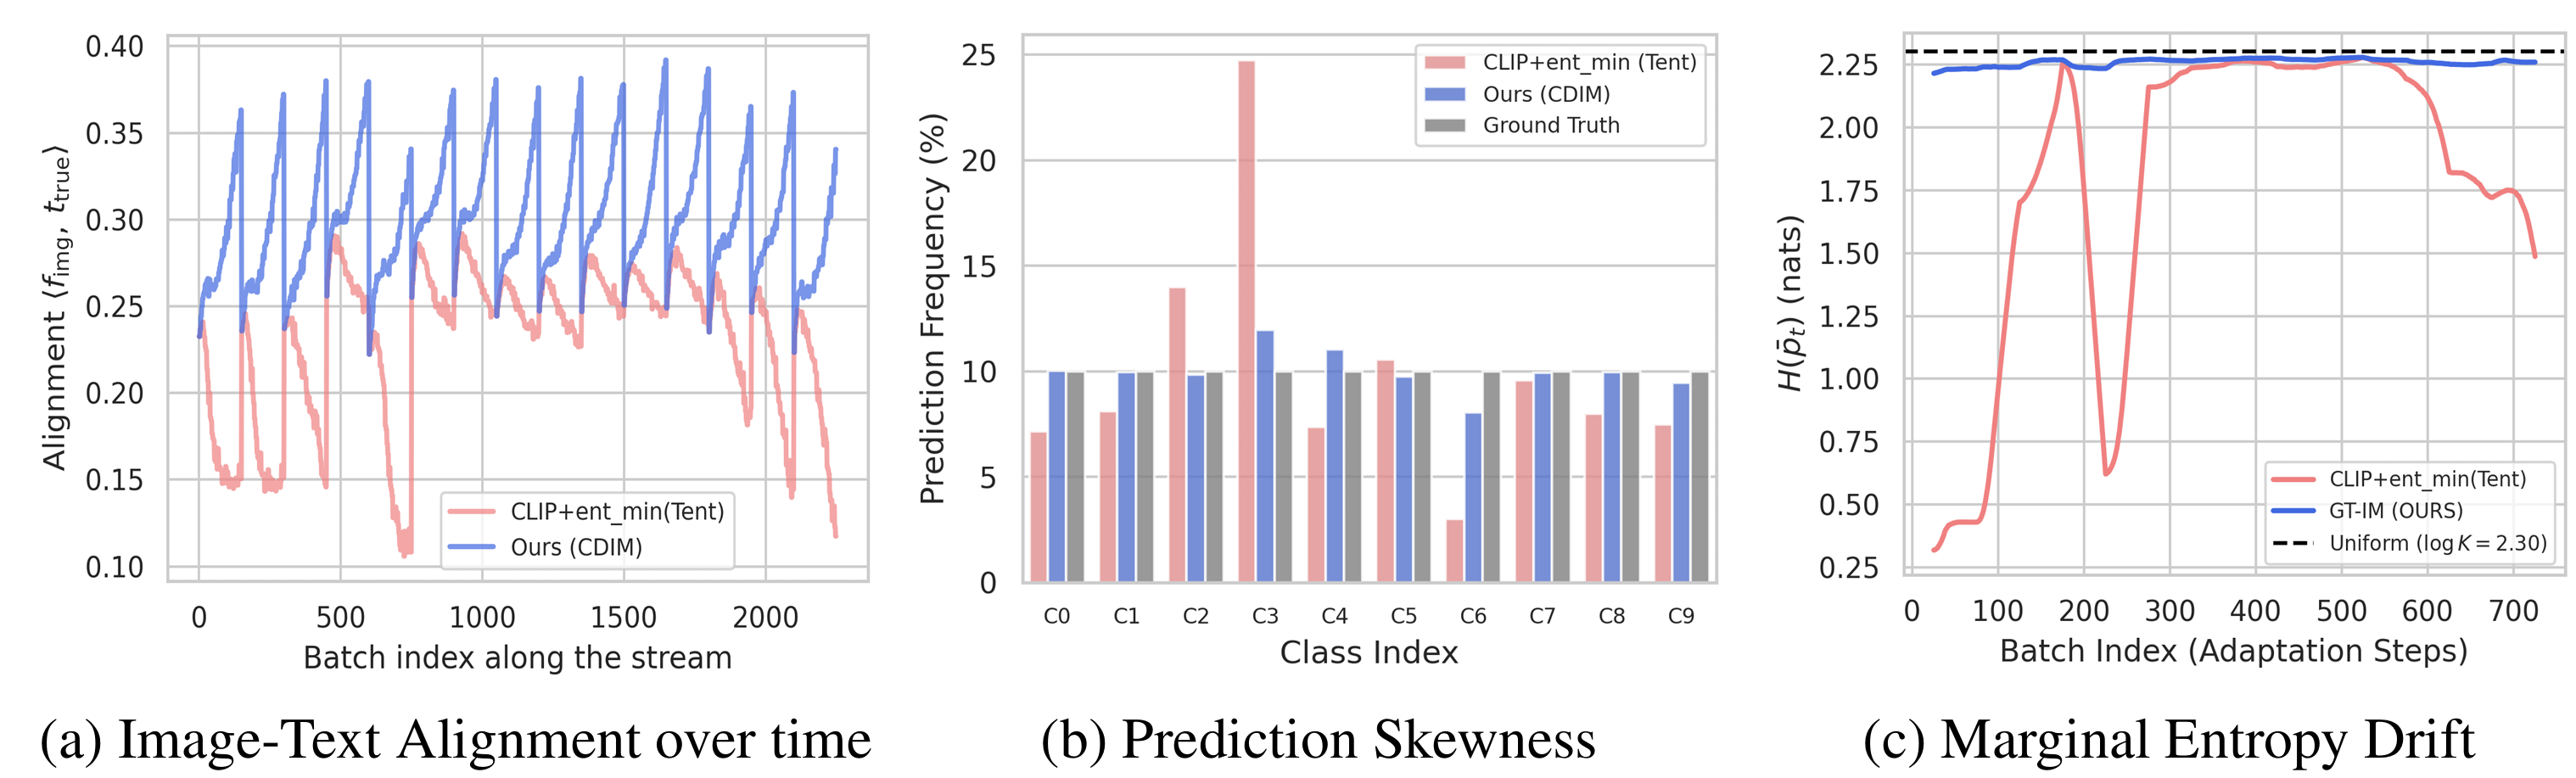
Adaptation Dynamics: On CIFAR10-C, CDIM keeps image-text alignment higher than CLIP+TENT and maintains a near-uniform prediction distribution.
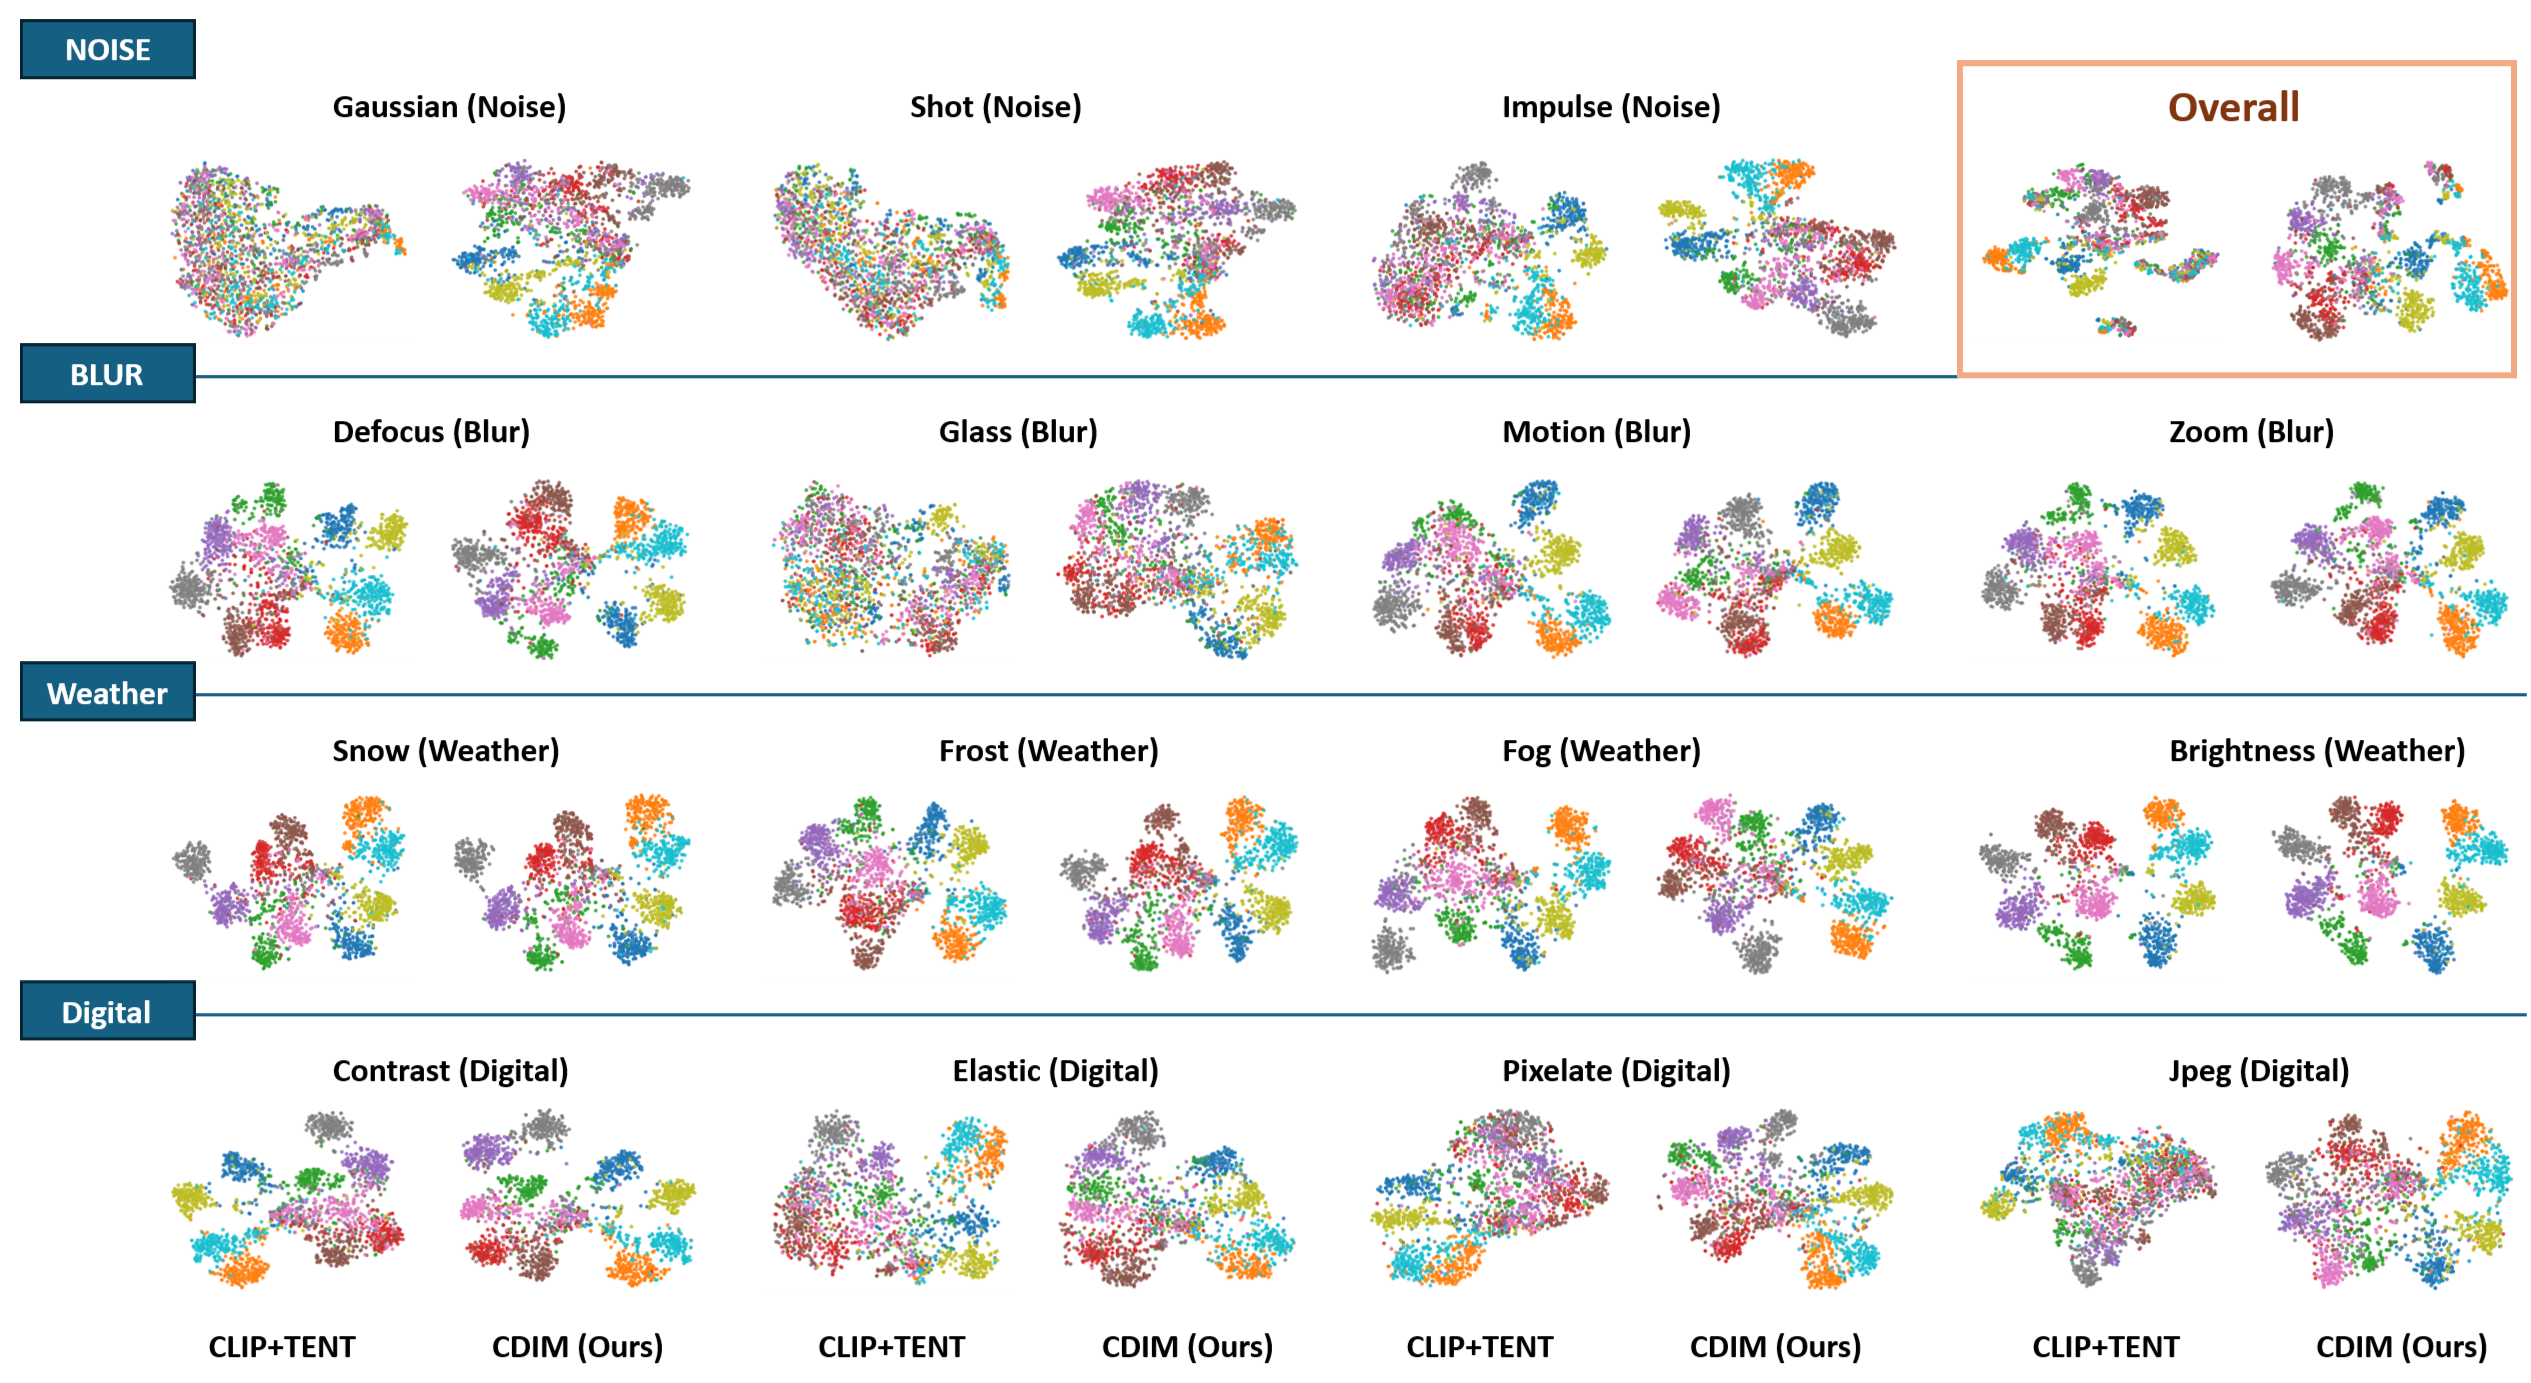
t-SNE Visualization: On CIFAR10-C under severe corruptions, CLIP+TENT embeddings collapse into a mixed cluster, whereas CDIM preserves clear class separation.
Proposed Method
- Representation level (cross-modal logit ensemble): A frozen self-supervised backbone (DINO v2) is added to CLIP as a complementary anchor. CLIP text prototypes are projected into the DINO feature space, and the two backbones are combined at the logit level to stabilize per-batch predictions against text-biased drift.
- Optimization level (gated test-time information maximization, GT-IM): GT-IM replaces standard entropy minimization by pairing per-sample sharpening with batch-level diversity. An adaptive confidence gate excludes unreliable samples to prevent noisy updates.
- Prediction level (online logit adjustment): The residual class-distribution skew is corrected using an exponential moving average (EMA) of the predicted class frequencies, which acts as a prior-balancing correction at inference time.
Poster
BibTeX
@misc{kim2026bridgingclipdinocrossmodal,
      title={Bridging CLIP with DINO: Cross-Modal Information Maximization for Online Test-Time Adaptation},
      author={Taehoon Kim and Wonjun Hwang and Hyunsouk Cho},
      year={2026},
      eprint={2611.04489},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2611.04489},
}